Best AI Code Review and Code Generation Tools in 2026
AI code review tools analyze source code and proposed changes to identify potential defects, security weaknesses, maintainability issues, and violations of development standards. Unlike AI code-generation tools, which help developers produce code, review tools examine whether the resulting implementation is correct, secure, maintainable, and consistent with the surrounding codebase.
This distinction has become increasingly important as developers use AI coding assistants and autonomous coding agents to generate functions, tests, refactors, and entire application components. Faster code creation does not automatically translate into better software. Generated code can contain incorrect assumptions, insecure patterns, inadequate error handling, or subtle business-logic defects that ordinary tests may not reveal.
The best AI code review tools in 2026 therefore do more than suggest cleaner syntax. They integrate into pull-request workflows, analyze repository context, identify potential problems, recommend fixes, and help engineering teams prioritize review effort.
However, tools differ significantly in their capabilities. Some focus on automated pull-request reviews, others provide repository-aware analysis, while platforms such as SonarQube, Semgrep, and Snyk strengthen code-quality and application-security controls.
This guide compares leading AI code review and code-generation tools, explains their strengths and limitations, and provides a practical framework for selecting, evaluating, and governing them in individual and enterprise development environments.
Table of contents
- Best AI Code Review and Code Generation Tools in 2026
- Frequently asked questions
- What is the best AI code review tool in 2026?
- Can AI review code automatically?
- Can ChatGPT or Claude review code?
- Is AI code review reliable?
- Can AI code review replace human reviewers?
- What is the difference between AI code review and static analysis?
- Which AI code review tools work with GitHub?
- Are there free AI code review tools?
- Can AI code review detect security vulnerabilities?
- Is it safe to connect AI code review tools to private repositories?
- What is the difference between an AI coding assistant and an AI code reviewer?
Want to go deeper into AI, AI governance, and practical enterprise applications? Explore my books for structured guides, frameworks, and practical insights on working with AI effectively.
🔥 Included with every PRO plan
Best AI code review tools in 2026: Quick answer
The best AI code review tool depends on where developers work, the type of defects they need to detect, the amount of repository context required, and the organization’s security and governance requirements.
| Tool | Particularly worth evaluating for |
|---|---|
| CodeRabbit | Dedicated AI pull-request reviews and developer feedback |
| Greptile | Repository-aware analysis and cross-file reasoning |
| GitHub Copilot | Teams already working primarily in GitHub |
| Qodo | Context-aware code review and engineering standards |
| Cursor Bugbot | Automated bug-focused reviews alongside AI coding |
| Graphite | Pull-request workflows, particularly stacked changes |
| PR-Agent | Customizable and self-managed PR automation |
| SonarQube | Code-quality enforcement and CI/CD quality gates |
| Semgrep | Security rules, vulnerability detection, and policy enforcement |
| Snyk | Application-security analysis and remediation workflows |
These are use-case-based candidates, not independently benchmarked rankings. Teams should evaluate them against representative repositories and known defects before making a purchase.
For many organizations, the most effective approach combines a coding assistant, a dedicated AI reviewer, deterministic security analysis, and human approval rather than relying on one product to perform every function.
Code generation vs. code completion vs. AI code review
Although these technologies increasingly overlap, they address different stages of software development. Understanding the distinction helps engineering teams avoid selecting an AI coding assistant when their actual requirement is automated code verification.
AI code completion
AI code completion predicts and suggests code while a developer is typing. Depending on the tool, suggestions may range from a single expression to a function body or a larger block of implementation.
For example, when a developer begins writing a Python function to validate an email address, a completion tool may suggest the remaining logic based on the function name, surrounding code, imported libraries, and comments.
The principal advantage is reduced effort for repetitive or familiar coding patterns. However, code completion is primarily a generation activity. A syntactically plausible suggestion may still fail to handle unusual inputs, security requirements, or application-specific constraints.
Tools such as GitHub Copilot and Tabnine provide capabilities in this category.
AI code generation
AI code generation converts natural-language instructions, specifications, or existing code context into new software artifacts. These can include functions, unit tests, database queries, API integrations, configuration files, and complete application components.
For instance, a developer might request an API endpoint that validates an incoming request, checks authorization, stores a record, and returns an appropriate response.
A generation tool can produce an initial implementation, but it may not understand all organizational requirements. It could omit rate limiting, choose an inappropriate authorization pattern, or make assumptions about the database schema.
Generated code must therefore be validated against functional requirements, architectural standards, tests, and security controls.
Agentic coding tools
Coding agents extend generation by planning and executing multi-step development tasks. Rather than returning only a code snippet, an agent may inspect files, modify several modules, run tests, investigate failures, and prepare a pull request.
For example, a coding agent assigned to upgrade an authentication library might locate affected dependencies, modify implementation files, update tests, and report unresolved compatibility issues.
This creates additional operational considerations. Agents may require repository access, shell execution, network connectivity, and permissions to modify files. Their actions should be constrained through sandboxing, least-privilege permissions, execution logs, and approval boundaries.
AI code review
AI code review analyzes existing code or proposed changes to identify potential problems before they reach production.
A reviewer may examine whether an API handles missing values, whether a database operation can fail unexpectedly, or whether a change introduces inconsistent error handling.
Unlike generation, the primary output is an assessment: findings, explanations, suggested corrections, and sometimes automated fixes.
The most useful reviews explain why a potential defect matters, reference the affected code, and provide enough context for a developer to verify the finding.
Automated pull-request review
Automated PR review applies AI analysis within a version-control workflow.
When a developer opens or updates a pull request, the review system can inspect the changed files, retrieve relevant repository context, summarize modifications, and publish comments.
This approach is valuable because it places AI feedback at a familiar engineering checkpoint, before code is merged.
However, not all PR reviewers analyze the same amount of context. A tool limited to the changed lines may miss problems caused by interactions with unchanged modules.
Static application security testing
Static application security testing (SAST) analyzes source code or related artifacts to identify potential vulnerabilities without executing the application.
Traditional SAST commonly uses rules, program analysis, and data-flow techniques. Generative AI reviewers use probabilistic reasoning over code and context.
The approaches complement each other. SAST can enforce known vulnerability patterns and security policies, while AI review may help explain findings or reason about implementation intent.
Neither method independently establishes that software is secure.
| Capability | Primary purpose | Typical output | Main limitation |
|---|---|---|---|
| Code completion | Assist writing code | Inline suggestions | Limited validation of correctness |
| Code generation | Create implementation artifacts | Functions, tests, modules | May misunderstand requirements |
| Coding agents | Execute multi-step development tasks | File changes, tests, PRs | Execution and permission risks |
| AI code review | Evaluate existing code | Findings and suggested fixes | False positives and missed defects |
| PR review automation | Review proposed changes in Git workflows | Inline PR comments and summaries | Context may be incomplete |
| SAST | Detect security-related code patterns | Vulnerability findings | Rules and analysis may miss business logic |
AI code review and code-generation tools: Comparison matrix
The following comparison focuses on product positioning and workflow fit. A tool’s precise capabilities may vary by edition, subscription, integration, and deployment model.
| Tool | Primary role | PR review | Code generation | Context and security focus |
|---|---|---|---|---|
| CodeRabbit | Dedicated AI reviewer | Core capability | Not its main purpose | Diff and repository-aware review |
| Greptile | Repository-aware AI reviewer | Core capability | Not its main purpose | Cross-file reasoning |
| GitHub Copilot | Coding assistant and reviewer | Supported | Core capability | GitHub-integrated review and coding |
| Qodo | AI code quality and review | Core capability | Supporting capabilities | Context-aware review |
| Cursor Bugbot | Automated bug reviewer | Core capability | Via separate Cursor coding features | Bug detection in code changes |
| Graphite | PR workflow and review | Supported | Secondary | Review workflow and change management |
| PR-Agent | Open-source PR automation | Core capability | Suggested code improvements | Configurable PR analysis |
| SonarQube | Code-quality analysis | Through development integrations | AI-assisted fixes in supported editions | Static analysis and quality gates |
| Semgrep | Application-security analysis | Through SCM/CI workflows | AI-assisted remediation in supported products | Security rules and code analysis |
| Snyk | Developer security | Through SCM/CI workflows | AI-assisted fixes in supported products | Code, dependency, and security risk |
| Claude Code | Agentic coding | Review workflows possible | Core capability | Repository reasoning and tool execution |
| OpenAI Codex | Agentic software development | Review workflows possible | Core capability | Code modification, testing and review |
Important: A security scanner that reports findings on a pull request is not necessarily equivalent to a generative AI reviewer that evaluates the PR’s broader implementation logic.
Best AI code review tools in 2026
1. CodeRabbit — dedicated AI pull-request review
CodeRabbit focuses on automated code reviews within developer workflows. Its central value is providing feedback on proposed changes before developers merge them into shared branches.
Rather than requiring developers to copy code into a chatbot, a dedicated review system can analyze pull requests and return comments where the team already collaborates.
Core capabilities
CodeRabbit is designed to help developers understand proposed changes, identify possible defects, and act on review suggestions. Its PR-centric approach makes it relevant for teams that want review coverage across frequent changes without requiring every developer to initiate a separate manual AI conversation.
The important distinction is that automated review is not equivalent to guaranteed defect detection. Teams must determine whether comments are technically correct, whether important findings are missed, and whether review volume is manageable.
Where it fits best
CodeRabbit is particularly worth evaluating for teams with established pull-request workflows and significant reviewer workloads.
For example, a SaaS engineering team processing dozens of pull requests daily may use automated reviews to identify straightforward defects before senior developers spend time evaluating architecture, business logic, and system-level implications.
Limitations
The value of automated review depends on how accurately the system understands repository context. A reviewer may flag a pattern that is intentional or miss a defect that depends on external services or undocumented business rules.
Teams should also test whether review comments are sufficiently actionable. Excessive low-severity suggestions can create more work than they save.
Selection consideration: Evaluate review precision, noise controls, repository permissions, integration coverage, and data-handling policies.
Official website: CodeRabbit
2. Greptile — repository-aware AI code review
Greptile emphasizes understanding code changes in the context of a larger repository.
This addresses an important weakness of diff-only reviews: a modification may appear correct when examined in isolation but cause problems elsewhere in the application.
Consider a developer changing a shared validation function. The pull request may modify only one file, while other modules depend on the function’s previous behavior. A repository-aware reviewer has a better opportunity to identify such dependencies when the relevant context is accessible.
Core capabilities
Greptile’s positioning centers on codebase understanding and AI-assisted review. This makes it a candidate for evaluating cross-file issues, architectural dependencies, and changes involving shared modules.
For large applications, repository context can be more valuable than a lengthy list of style recommendations.
Where it fits best
Greptile is particularly relevant to engineering teams working with mature applications, shared libraries, and codebases where changes have consequences beyond the modified files.
Limitations
Repository-aware analysis does not guarantee complete system understanding. Correctness may depend on runtime configuration, external services, historical decisions, or business requirements absent from the repository.
Organizations must also examine what source-code content is processed, how access is controlled, and whether the deployment arrangement meets internal policies.
Selection consideration: Test cross-file defect detection using known problems in unchanged files that interact with the proposed modification.
Official website: Greptile
3. GitHub Copilot code review — integrated GitHub workflows
GitHub Copilot combines AI-assisted coding with code-review capabilities inside GitHub’s development environment.
This makes it attractive for organizations already using GitHub for source control, pull requests, issue management, and development collaboration.
GitHub’s documentation describes a workflow in which developers request a Copilot review on a pull request, inspect comments, and apply suggested changes where appropriate. Copilot reviews can also be configured to run automatically. GitHub Docs+1
Core capabilities
Copilot supports code suggestions, conversational assistance, agentic development workflows, and code review. For review, developers can receive comments tied to a pull request and use suggested changes to address identified issues.
GitHub also supports repository-level customization and review-related instructions. This is useful when an organization wants reviewers to consider its coding conventions, architectural constraints, or project-specific expectations.
Where it fits best
Copilot code review is a practical starting point for GitHub-centric teams that already use Copilot for code generation.
For example, a developer may generate a new API handler using Copilot, write and execute tests, submit a pull request, and request Copilot review before assigning the change to a human reviewer.
Limitations
Copilot’s review output should not be treated as definitive proof of correctness. Review comments still require verification, and teams should not assume every defect will be detected.
Its approval behavior also deserves attention. GitHub documentation indicates that Copilot reviews normally provide comments rather than required approvals, although configurable approval capabilities are available. Organizations should explicitly control whether AI approval can satisfy merge requirements. GitHub Docs+1
Selection consideration: Evaluate review customization, billing, organizational controls, and whether the GitHub-native experience eliminates the need for a separate reviewer.
Official documentation: GitHub Copilot code review
4. Qodo — context-aware code quality and review
Qodo focuses on AI-assisted software quality, with review workflows intended to help developers identify issues and improve code changes.
Its relevance lies in moving beyond generic suggestions toward feedback informed by repository context and engineering conventions.
Core capabilities
Qodo’s code-review offerings are designed around analyzing changes, producing feedback, and supporting code-quality workflows.
For enterprise teams, the evaluation should focus on whether the tool can apply relevant development standards consistently and whether it distinguishes material defects from stylistic preferences.
For example, an organization might want AI review to identify missing validation, inconsistent exception handling, or deviations from an established service architecture.
Where it fits best
Qodo is worth evaluating for teams seeking a dedicated AI review capability that can be integrated with existing engineering practices.
Limitations
The effectiveness of contextual review depends on the quality of available repository information and how well the system interprets organizational conventions.
Teams should verify current product editions, integrations, and deployment options before adoption.
Official website: Qodo
5. Cursor Bugbot — bug-focused automated review
Cursor Bugbot extends the Cursor ecosystem’s emphasis on AI-assisted development into code-review workflows.
Cursor’s broader development environment helps developers write and modify code, while Bugbot is positioned around finding potential bugs in proposed changes.
This distinction is important. Code generation and bug review may be offered within the same ecosystem, but they remain separate engineering activities.
Core capabilities
Bug-focused review can help identify incorrect conditions, missing edge-case handling, and potential implementation problems.
For example, an AI-generated change to an order-processing service may pass syntax checks while mishandling an unusual order state. A reviewer can attempt to detect that logical inconsistency before merge.
Where it fits best
Cursor Bugbot is relevant to teams already using Cursor and organizations seeking automated feedback on frequent code changes.
Limitations
A bug-focused reviewer should not be assumed to replace comprehensive security scanning, architectural review, or business-rule validation.
Teams should also test whether it provides meaningful findings beyond those already detected by tests and static analysis.
Official website: Cursor
6. Graphite — AI review within pull-request workflows
Graphite approaches review as part of a broader developer workflow rather than as an isolated code-analysis activity.
It is particularly relevant to teams using stacked pull requests, where a larger change is divided into smaller, dependent reviews.
Core capabilities
Graphite’s workflow orientation can help teams manage changes, review dependencies, and reduce friction around pull-request coordination.
Smaller, focused pull requests can also make AI feedback easier to interpret because each change has a more limited scope.
Where it fits best
Graphite is worth evaluating when pull-request management itself is a significant bottleneck, especially in teams that regularly work with dependent changes.
Limitations
A workflow platform and a defect-detection system solve related but different problems. Organizations should evaluate Graphite’s review accuracy independently of its productivity and PR-management capabilities.
Official website: Graphite
7. PR-Agent — customizable open-source pull-request automation
PR-Agent is an option for engineering teams that want greater control over automated review workflows.
An open-source approach can be attractive when organizations need to customize prompts, select model providers, integrate with internal systems, or operate components within their own infrastructure.
Core capabilities
PR-Agent can be used to build automated pull-request assistance, including review-related analysis and change descriptions.
Because it is an open-source project, engineering teams can inspect the implementation and adapt supported workflows to their needs.
Where it fits best
PR-Agent is relevant to platform-engineering teams, internal developer-platform initiatives, and organizations with the technical resources to maintain customized AI review automation.
Limitations
Self-management introduces responsibilities that a SaaS provider might otherwise handle. These include model access, credentials, upgrades, monitoring, infrastructure, and security controls.
Open-source availability does not automatically mean the complete workflow is private. If the deployment sends source-code context to an external model API, that data still crosses an organizational boundary.
Official repository: PR-Agent on GitHub
AI-assisted code security and static analysis tools
Dedicated AI reviewers should be distinguished from security and code-quality platforms. These products can report findings in pull requests, but their underlying analysis methods, objectives, and enforcement mechanisms differ.
8. Snyk — developer security and remediation
Snyk focuses on identifying and addressing application-security risks throughout development.
Its offerings cover security concerns such as vulnerable dependencies and source-code weaknesses, with AI-assisted capabilities in parts of its portfolio.
Snyk is particularly useful when an organization needs to connect developer feedback with a structured application-security program.
For example, an AI coding assistant may generate a service that uses an outdated dependency. A general AI reviewer might comment on implementation quality, while dependency-security analysis can identify a known vulnerable package version.
The two findings are complementary.
Where it fits best: Development teams that need security findings, remediation workflows, and integration with DevSecOps processes.
Limitation: Security scanning cannot establish that the application’s business logic is correct. Teams still need tests, design review, and human judgment.
Official website: Snyk
9. Semgrep — security rules and AI-assisted analysis
Semgrep provides code-security analysis with a strong emphasis on developer workflows and configurable detection.
Rule-based analysis is valuable because organizations can define and enforce security requirements independently of the variability of generative-model responses.
For example, a security team might enforce rules against unsafe deserialization, insecure cryptographic usage, or prohibited API patterns.
Such checks can run repeatedly in CI/CD pipelines and generate findings tied to code changes.
Semgrep’s broader platform also includes AI-related capabilities, but buyers should distinguish those from its underlying static-analysis functionality.
Where it fits best: Security engineering teams requiring configurable detection, consistent policies, and integration with development workflows.
Limitation: Static rules and automated analysis may miss vulnerabilities that depend on application-specific business logic or runtime behavior.
Official website: Semgrep
10. SonarQube — code-quality governance and AI code assurance
SonarQube helps organizations analyze source code for maintainability, reliability, and security-related issues.
It is particularly relevant when engineering teams need repeatable quality standards rather than relying entirely on probabilistic AI feedback.
SonarQube’s AI Code Assurance capabilities support applying quality standards to projects containing AI-generated code. Its documentation also describes AI-assisted fix suggestions in supported editions. Sonar Documentation+1
Core capabilities
SonarQube can be integrated into development pipelines to analyze code and enforce quality gates.
For example, an organization may configure a quality gate to prevent merging code that introduces unacceptable reliability or security findings.
This provides a more structured enforcement mechanism than simply asking an AI reviewer whether a pull request looks acceptable.
Where it fits best
SonarQube is valuable for organizations seeking centralized code-quality governance, consistent standards, and CI/CD enforcement.
Limitations
Passing a quality gate does not prove that the application behaves correctly in every scenario.
A system may meet static-analysis standards while containing incorrect business logic, authorization assumptions, or architectural decisions.
Official website: SonarQube
Best AI code-generation and agentic coding tools in 2026
AI code review is only one part of the software development lifecycle. Coding assistants and agents remain important because they influence how code is created, modified, tested, and submitted for review.
The original article covered GitHub Copilot, Claude, Amazon CodeWhisperer, Tabnine, Sourcegraph Cody, and Replit. These topics remain relevant, but their 2026 positioning needs refinement.
In particular, Amazon CodeWhisperer should no longer be presented as a standalone current product: AWS incorporated it into Amazon Q Developer in April 2024. AWS Prescriptive Guidance+1
11. Claude Code — agentic coding and complex development tasks
Claude Code is an agentic development tool built around Anthropic’s Claude models.
Unlike conventional code completion, an agentic workflow can involve inspecting a repository, understanding a requested change, modifying multiple files, running commands, and iterating on test failures.
For example, a developer might ask Claude Code to update an authentication integration across several services. The agent could examine existing implementations, identify affected files, suggest modifications, and run available tests.
The value lies in coordinating related engineering tasks rather than producing isolated snippets.
Strengths and applications
Claude Code is particularly relevant to complex refactoring, debugging, repository exploration, test generation, and development tasks that require multiple steps.
Its review capabilities can also support code inspection. However, an interactive coding agent and a dedicated PR-review service should not be assumed to have identical workflows, access controls, or pricing.
Limitations
Agentic execution introduces risks beyond incorrect generated text. An agent may modify unexpected files, execute commands with side effects, or make changes based on incomplete repository understanding.
Organizations should use restricted permissions, sandboxed execution where appropriate, explicit approval for consequential operations, and reviewable change histories.
Best for: Developers and engineering teams seeking assistance with multi-file changes and complex development workflows.
Official documentation: Claude Code documentation
12. OpenAI Codex — agentic software development
OpenAI Codex supports AI-assisted software engineering tasks such as code modification, debugging, testing, and working with repositories.
Its significance is the shift from generating a suggested answer toward completing a bounded development task.
For example, a developer may assign an agent to investigate a failing test, locate the affected implementation, propose a correction, and produce a change for review.
In such workflows, developers spend more time specifying requirements, inspecting results, and validating changes.
Strengths and applications
Codex is relevant to codebase exploration, feature implementation, bug fixing, refactoring, and test-related workflows.
It can also assist with code review, but organizations should distinguish an agent’s ability to analyze code from a dedicated automated reviewer integrated into every pull request.
Limitations
Coding agents can generate plausible changes that pass some tests while violating requirements not represented in the test suite.
Their access to repositories, tools, execution environments, and external services also requires governance.
Best for: Teams experimenting with agent-assisted software engineering and controlled task delegation.
Official website: OpenAI Codex
13. Amazon Q Developer — AWS-integrated coding assistance
Amazon Q Developer combines AI-assisted code generation with capabilities designed for AWS development environments.
AWS incorporated the former CodeWhisperer capabilities into Amazon Q Developer, including inline coding suggestions and security-related functionality. Amazon Q Developer supports integrations with environments such as Visual Studio Code and JetBrains IDEs. AWS Prescriptive Guidance+1
Strengths and applications
Amazon Q Developer is particularly relevant to teams building applications using AWS services, SDKs, and infrastructure.
For example, a developer implementing an AWS Lambda function may use the assistant to generate service integrations, explain AWS-related code, or support development and troubleshooting.
It is also useful when developers need assistance understanding AWS APIs and development patterns.
Limitations
AWS integration is an advantage for AWS-centric teams but does not automatically make the tool the best choice for every programming language or repository workflow.
Generated infrastructure and security configurations require particular care. Incorrect IAM permissions, network configurations, or resource policies can create operational and security risks.
Best for: AWS-focused development teams.
Official documentation: Amazon Q Developer
14. Tabnine — enterprise privacy and deployment flexibility
Tabnine emphasizes AI-assisted development with enterprise deployment and privacy considerations.
This positioning makes it relevant to organizations that cannot adopt every cloud-based coding assistant without first assessing source-code confidentiality, data processing, and intellectual-property exposure.
Strengths and applications
Tabnine provides AI coding assistance and offers enterprise-oriented deployment approaches.
For organizations handling sensitive source code, the important question is not simply whether a tool has a privacy policy. It is whether the actual deployment satisfies the organization’s data-boundary and access-control requirements.
A private deployment may be attractive for a financial institution developing proprietary risk models or a healthcare technology company maintaining regulated application components.
Limitations
Private deployments can introduce infrastructure costs, operational responsibilities, and model-management requirements.
The quality of coding suggestions also depends on the selected models, repository context, and supported development environments.
Best for: Enterprises prioritizing deployment control and source-code privacy.
Official website: Tabnine
15. Cursor — AI-assisted coding environment
Cursor is an AI-oriented development environment that integrates code understanding, generation, and editing into the developer workflow.
Its principal value is reducing the friction between understanding existing code and modifying it.
For example, a developer may ask Cursor to explain a module, generate tests for a function, or update several related files.
Cursor Bugbot, discussed earlier, addresses the separate requirement of reviewing changes for potential defects.
Strengths and applications
Cursor is particularly relevant for developers who want AI assistance closely integrated with editing and repository navigation.
Its coding workflows can support feature development, refactoring, and debugging.
Limitations
An AI-oriented editor does not eliminate the need for independent code validation. Developers must verify suggested changes, particularly when multiple files are modified.
Organizations should also evaluate how editor integrations access source code and how data-processing controls apply.
Best for: Developers seeking an integrated AI coding environment.
Official website: Cursor
What about Sourcegraph Cody and Replit?
The original article also covered Sourcegraph Cody and Replit Ghostwriter.
Both deserve different treatment in the updated article.
Sourcegraph: Its repository search and code-intelligence capabilities remain relevant to understanding large codebases. However, the availability and positioning of Cody and related AI products should be verified against current Sourcegraph documentation before retaining a standalone Cody recommendation.
Replit: Replit remains relevant to browser-based application development and agent-assisted prototyping. The updated article should focus on its current Agent experience rather than treating Ghostwriter as the primary contemporary product identity.
These products can be mentioned as alternatives, but they should not displace dedicated code-review tools in an article targeting AI code review searches.
How AI code review works in the pull-request lifecycle
Automated code review is most effective when it operates within an established software development process.
The objective is not to generate as many comments as possible. It is to identify meaningful defects early enough for developers to correct them without creating unnecessary delays.
1. A developer creates or modifies code
A developer writes code manually or uses an AI coding assistant to generate an initial implementation.
The change might involve a new API endpoint, database migration, authentication workflow, or bug fix.
At this stage, developers should validate requirements, execute local tests, and inspect generated code before submitting it for review.
2. The developer opens a pull request
The pull request provides a structured representation of proposed changes.
It usually includes the changed files, commit history, description, and links to relevant issues.
An AI reviewer can use this information as the starting point for analysis.
A clear PR description is valuable because code alone may not reveal the intended business behavior.
3. The AI reviewer examines the changes
The reviewer analyzes the diff and, depending on its capabilities and configuration, retrieves additional context.
This may include unchanged functions, related modules, tests, configuration files, and repository instructions.
The reviewer attempts to identify problems such as incorrect conditions, missing validation, error-handling gaps, and unsafe assumptions.
4. The system produces findings
Review findings may appear as inline comments, summaries, severity assessments, or suggested code changes.
Useful findings should identify the affected code, explain the potential consequence, and propose a reasonable way to investigate or resolve the issue.
For example, rather than stating that an API handler has poor error handling, a useful review might explain that a database exception can cause an unintended response or leave an operation partially completed.
5. Developers verify and resolve findings
Developers should not automatically accept every AI suggestion.
They need to determine whether the reported issue is real, whether the proposed correction preserves intended behavior, and whether the change introduces additional risks.
Some findings may be false positives. Others may reveal genuine problems that require more substantial architectural changes.
6. Automated quality and security checks run
AI review should complement, not replace, automated tests and deterministic analysis.
CI/CD pipelines may execute unit tests, integration tests, static analysis, dependency scanning, secret detection, and policy checks.
These controls provide different forms of evidence about the proposed change.
7. Human reviewers make the final assessment
Human reviewers remain responsible for evaluating whether the implementation satisfies requirements, aligns with the system architecture, and introduces acceptable risk.
For high-risk changes, organizations may require approval from designated code owners, security engineers, or domain specialists.
8. The change is merged under defined controls
A pull request should be merged only after the applicable quality gates and approval requirements are satisfied.
The organization should retain appropriate records of review findings, test outcomes, approvals, and exceptions.
This creates a review process that is repeatable, auditable, and aligned with software-delivery governance.
Why repository context matters in AI code review
Repository context is one of the most important factors influencing the usefulness of automated code review.
A code change may be correct when viewed in isolation but incorrect when considered within the broader application.
Consider an e-commerce platform where a developer changes the behavior of a discount-calculation function.
The modified function may compile successfully and pass its local unit tests. However, an unchanged checkout service may depend on the previous behavior.
A reviewer that examines only the changed lines may not detect the incompatibility.
Different levels of context
| Context level | What the reviewer examines | Potential limitation |
|---|---|---|
| Diff-level | Added and removed lines | Misses dependencies outside the change |
| File-level | Entire modified file | May overlook interactions with other modules |
| Repository-level | Related files, tests, and dependencies | May still lack runtime or business context |
| Cross-repository | Dependencies across services or repositories | Requires broader access and reliable dependency understanding |
| Runtime/business context | Specifications, logs, configurations, requirements | Often unavailable or incomplete |
Repository-aware analysis is especially useful for changes involving shared APIs, authentication, common libraries, data models, and service interfaces.
However, access to more context does not automatically improve review quality. Excessive or irrelevant context can distract a model, increase cost, or introduce conflicting information.
Organizations should therefore evaluate whether a tool retrieves the right context, not merely whether it claims to support whole-repository analysis.
AI code review vs. static analysis vs. security scanning
AI code review, static analysis, and security scanning should be treated as complementary controls.
A generative AI reviewer may reason about the apparent purpose of a function and identify an inconsistency. A static-analysis tool may detect a prohibited API pattern. A dependency scanner may identify a vulnerable library version.
Each tool addresses a different class of risk.
| Capability | Generative AI review | Static analysis | Security scanning |
|---|---|---|---|
| Business-logic reasoning | Potentially useful, context-dependent | Usually limited | Usually limited |
| Known code patterns | Can identify some | Strong for supported rules | Strong for supported security patterns |
| Dependency vulnerabilities | Not a reliable primary control | Depends on product | Dedicated SCA tools |
| Explanatory feedback | Natural-language explanations | Rule descriptions | Findings and remediation guidance |
| Deterministic enforcement | Limited | Often supported | Often supported |
| False positives | Possible | Possible | Possible |
| Human verification | Required | Required for material findings | Required for material findings |
Why a layered approach works better
Consider an AI-generated authentication endpoint.
A generative reviewer might notice that a role check appears inconsistent with the surrounding application.
Static analysis might detect unsafe input handling or a risky coding pattern.
Dependency scanning might identify a known vulnerability in an authentication library.
Tests might reveal that an unauthorized user can access a protected resource.
A human security reviewer can then evaluate whether the overall authorization design is appropriate.
These findings provide different forms of assurance. No single tool can reliably replace all the others.
IDE integration, repository integration, and programming-language support
Integration is not merely a convenience feature. It determines when developers receive feedback, what context a tool can access, and whether the tool fits existing workflows.
IDE integration
IDE-based assistants operate close to the point where code is written.
Common environments include Visual Studio Code and JetBrains IDEs. Some tools also support terminal-based workflows.
IDE integration is particularly valuable for code completion, conversational debugging, refactoring, and early feedback.
However, an IDE assistant may not have the same repository-level permissions or review context as a system connected directly to the code host.
Repository integration
Repository integrations allow tools to respond to pull-request events and access relevant source-code information.
Organizations should verify support for their actual environment, including:
- GitHub and GitHub Enterprise
- GitLab and self-managed GitLab
- Bitbucket Cloud and Data Center
- Azure DevOps
- Private or internally hosted Git services
Support for a vendor’s cloud-hosted service does not automatically imply support for its self-managed edition.
The distinction matters for enterprises with internal source-control infrastructure.
CI/CD integration
CI/CD integration is important when review findings need to influence merge decisions.
For example, an organization might allow informational AI comments but block merging when deterministic security analysis detects a critical vulnerability.
A mature workflow separates advisory findings from mandatory controls.
Supported programming languages
Language support should be evaluated in terms of actual analysis quality, not simply whether a product accepts files with a particular extension.
A tool may generate reasonable Python code while struggling with a less common language or framework.
Similarly, a reviewer may understand ordinary JavaScript functions but miss framework-specific security implications.
Teams should test tools against their actual stack, including application code, infrastructure-as-code, configuration files, and test frameworks.
For enterprise adoption, representative evaluation is more useful than a long vendor-published list of supported languages.
False positives, hallucinations, and review noise
One of the biggest operational challenges in AI code review is distinguishing meaningful findings from unnecessary or incorrect feedback.
A reviewer that generates many comments may appear thorough. However, if most comments are irrelevant, developers must spend additional time investigating and dismissing them.
This can reduce productivity and weaken trust in the review process.
False positives
A false positive occurs when the tool reports a problem that is not actually present.
For example, an AI reviewer may flag a missing null check even though the value is guaranteed by a validated upstream contract.
If the reviewer does not understand that contract, it may recommend unnecessary defensive code.
False positives become particularly costly when they repeatedly appear across routine pull requests.
Hallucinated defects
A hallucinated defect occurs when the model incorrectly infers behavior, dependencies, or execution paths.
For example, it might claim that a function calls an unsafe API even though the referenced call is absent from the relevant execution path.
Such findings can appear convincing because they are expressed in technical language.
Developers should verify the underlying code path rather than accepting the explanation at face value.
Excessive stylistic feedback
Some review systems produce comments about naming, formatting, or minor stylistic preferences.
These comments may be useful in limited circumstances, but they can distract reviewers from security, correctness, and reliability issues.
Formatting and straightforward coding conventions are often better enforced through linters and automated formatting tools.
Incorrect suggested fixes
A suggested fix can resolve the reported issue while introducing a different problem.
For example, an AI reviewer might recommend adding exception handling that unintentionally suppresses an important failure.
The resulting code may appear more defensive while making production problems harder to detect.
Suggested fixes should therefore be reviewed, tested, and evaluated for unintended consequences.
How to reduce review noise
Organizations can improve review quality by establishing clear severity criteria, configuring repository-specific instructions, and defining which categories of feedback deserve attention.
A practical approach is to prioritize findings that could affect correctness, security, data integrity, reliability, or material maintainability.
Low-value stylistic suggestions can be handled separately or suppressed when deterministic tooling already enforces the relevant standard.
The goal should be more verified, actionable findings per review, not simply more comments.
Pricing and cost considerations
AI code review tools use different commercial models. Comparing subscription prices without understanding how usage is measured can produce misleading conclusions.
Some products use per-developer subscriptions. Others may charge for review activity, model consumption, credits, or enterprise deployment.
Self-managed tools may avoid a SaaS subscription while introducing infrastructure and operational costs.
Common pricing models
| Pricing model | How it works | What buyers should examine |
|---|---|---|
| Per-user subscription | Charge for each licensed developer | Active seats, minimum commitments, plan limits |
| Usage-based | Charge according to consumed resources | Review frequency, model usage, overages |
| Per-review or credit-based | Charge for review activity or credits | PR volume, repeated reviews, credit consumption |
| Enterprise contract | Negotiated commercial arrangement | Security controls, support, deployment, SLAs |
| Open-source/self-managed | Software may be available without license fees | Model API, hosting, maintenance, engineering effort |
Pricing model descriptions are general. Confirm each vendor’s current billing structure and entitlements before purchase.
Why cost per meaningful review matters
Suppose a team processes 500 pull requests each month.
Tool A costs less per developer but produces substantial review noise. Tool B has a higher subscription price but provides fewer, more actionable findings.
The lower subscription price does not necessarily represent better value.
A useful cost calculation is:
\[ \text{Cost per actionable finding} = \frac{\text{Total review operating cost}} {\text{Verified actionable findings}} \]
Total operating cost should include subscription or usage fees, infrastructure expenses, configuration and maintenance, and developer time spent triaging findings.
This measure is imperfect because findings differ in severity. A critical authorization defect has greater value than a minor maintainability improvement.
Organizations should therefore evaluate cost alongside defect severity, developer effort, and escaped defects.
Free and open-source options
Free plans and open-source tools can be useful for individual developers, public repositories, and early evaluation.
PR-Agent is one option for teams that want to investigate self-managed review automation.
However, free access may involve usage restrictions, reduced governance capabilities, or additional infrastructure responsibilities.
Enterprise buyers should confirm whether features such as SSO, audit logs, private deployment, and administrative controls require paid editions.
Privacy, code ownership, and intellectual-property risks
AI coding and code-review tools often require access to proprietary source code.
This creates a different risk profile from using an AI assistant to draft general-purpose text.
Source code may reveal business logic, internal architecture, security controls, proprietary algorithms, and information about connected systems.
Organizations should understand how this information is accessed, processed, retained, and protected.
Source-code processing and data boundaries
The first question is whether source-code content leaves the organization’s controlled environment.
A cloud-hosted review service may need to process diffs or repository context using external infrastructure.
Some enterprise offerings provide alternative deployment arrangements, but the availability and scope of these arrangements vary.
Organizations should establish which repositories and data classifications can be processed by each approved tool.
Model training and retention
A vendor’s statement that it does not train models on customer data should be evaluated alongside its actual retention and subprocessors policies.
Important questions include whether prompts, code snippets, logs, and generated outputs are stored; how long they are retained; and whether third-party model providers process the data.
Terms may differ across consumer, team, enterprise, and API offerings.
Access control and auditability
AI tools should receive only the repository permissions necessary for their intended function.
A reviewer that only needs to inspect pull requests should not automatically receive unrestricted write access across an organization’s repositories.
Enterprises should assess authentication, SSO, RBAC, audit logs, token management, and access revocation.
Generated-code ownership and licensing
AI-generated code can raise intellectual-property and licensing questions.
Organizations should examine contractual terms governing generated outputs, potential similarity to existing licensed code, and any available intellectual-property protections.
They should also establish policies for reviewing substantial generated snippets and handling open-source dependencies.
Ownership and copyright questions depend on jurisdiction, contract terms, and the circumstances of creation. Vendor marketing statements should not be treated as legal conclusions.
Unauthorized tool usage
Employees may use personal AI accounts or unapproved extensions to process company code.
This creates potential exposure outside approved enterprise controls.
A practical governance program should therefore combine clear policies with approved alternatives, technical restrictions where appropriate, and developer education.
Self-hosting, private cloud, and enterprise deployment
Deployment architecture is an important selection criterion for organizations handling sensitive code or operating under regulatory obligations.
The available deployment options can include SaaS, private cloud, customer-managed infrastructure, and self-hosted arrangements.
These terms are not interchangeable.
| Deployment model | Description | Main tradeoff |
|---|---|---|
| SaaS | Vendor operates the service | Easier adoption, less infrastructure control |
| Private cloud | Dedicated or isolated cloud arrangement | Greater isolation, potentially higher cost |
| Customer VPC | Components operate within a customer-controlled cloud environment | More operational responsibility |
| Self-hosted | Organization operates the software | Greater control, maintenance burden |
| On-premises | Runs on organization-managed infrastructure | Infrastructure and operational complexity |
| Air-gapped | Designed to operate without external network connectivity | Model, update, and integration constraints |
A self-hosted review application may still use an external model API. Therefore, deployment location alone does not establish that code remains private.
Organizations must examine the complete data path, including model inference, telemetry, logging, updates, and third-party integrations.
When private deployment matters
Private deployment may be particularly relevant for financial institutions, healthcare technology companies, government organizations, defense-related systems, and businesses protecting proprietary intellectual property.
However, a private deployment should be justified by actual security and compliance requirements.
For a small team working primarily on public repositories, a managed SaaS reviewer may be more practical than maintaining an internal review platform.
For a regulated enterprise, the additional operational burden may be justified by requirements for data control, access restrictions, and auditability.
How enterprises should govern AI coding and code-review tools
Enterprise adoption requires more than purchasing licenses and enabling integrations.
AI coding systems can generate changes, inspect proprietary repositories, execute commands, and recommend modifications to security-sensitive code.
Governance must therefore address both the content of AI-generated code and the actions that AI-enabled tools are permitted to perform.
Establish an approved-tool policy
Organizations should maintain an inventory of approved AI development tools.
For each tool, the inventory should identify its business owner, supported use cases, deployment model, data-handling conditions, access permissions, and applicable restrictions.
A coding assistant approved for public documentation repositories may not be appropriate for a repository containing proprietary security implementations.
Apply risk-based controls
Not every AI-assisted coding activity requires the same level of oversight.
| Risk level | Example | Appropriate controls |
|---|---|---|
| Low | Test scaffolding, non-sensitive boilerplate | Standard review and automated tests |
| Moderate | Application features and internal APIs | AI review, tests, human PR approval |
| High | Authentication, payments, infrastructure permissions | Security review, stricter tests, mandatory code owners |
| Critical | Safety-critical or regulated decision logic | Independent validation, restricted AI use, formal approval |
The objective is proportional governance. Excessive controls on low-risk tasks can reduce productivity, while insufficient controls on critical code can expose the organization to material harm.
Separate agent permissions from developer permissions
A coding agent should not automatically inherit every permission available to the developer initiating the task.
For example, an agent that needs to modify a feature branch does not necessarily need permission to deploy production infrastructure or access unrelated repositories.
Least-privilege permissions, scoped credentials, sandboxed execution, and approval checkpoints reduce the consequences of unexpected behavior.
Maintain human accountability
AI reviewers may help identify defects, but responsibility for software quality remains with the organization and its engineering teams.
For high-risk changes, human approval should remain an enforceable control.
Organizations should also define who can accept AI-generated fixes, override findings, and approve exceptions.
Integrate governance into CI/CD
Policies are more effective when implemented as technical controls.
Examples include required tests, branch protection, security gates, code-owner approval, dependency scanning, and restrictions on direct changes to protected branches.
AI review findings can inform decisions, but mandatory security requirements should not depend solely on a generative model’s judgment.
Monitor performance and reassess tools
Governance should continue after deployment.
Engineering leaders should monitor review usefulness, false positives, security findings, developer feedback, and operational costs.
Tool capabilities and data-handling terms may change, making periodic reassessment necessary.
For a broader enterprise perspective, see how enterprises build AI governance frameworks.
How to choose the right AI code review tool
Choosing an AI code review tool should begin with the organization’s engineering requirements rather than a vendor ranking.
A tool that works well for an individual developer may be unsuitable for a regulated enterprise. Similarly, a product that excels at repository-wide reasoning may be unnecessary for a team maintaining small, independent applications.
The following framework can help teams make a structured decision.
Step 1: Define the primary requirement
Determine whether the organization needs faster pull-request feedback, better defect detection, security analysis, code generation, or improved review coordination.
These objectives require different capabilities.
For example, a team struggling with long PR queues may benefit from automated review, while a team experiencing recurring security vulnerabilities may need stronger SAST and dependency scanning.
Step 2: Examine the existing development environment
Identify where developers write code, where repositories are hosted, and how changes move through CI/CD.
A tool that integrates naturally with existing systems is generally easier to adopt than one requiring developers to change their established workflow.
However, integration convenience should not outweigh critical security or quality requirements.
Step 3: Determine the required repository context
Evaluate whether the reviewer needs to understand only changed files or broader dependencies.
Small, independent modules may be adequately reviewed using limited context. Large applications with shared libraries and interconnected services may require deeper repository analysis.
Step 4: Assess security and privacy requirements
Identify the sensitivity of source code and any restrictions on external processing.
Examine the vendor’s data-handling terms, model providers, access controls, retention policies, and available deployment options.
Security requirements should be established before a tool is connected to production repositories.
Step 5: Evaluate review quality
Test each candidate using representative pull requests containing known defects.
Measure whether the tool identifies meaningful issues, explains them accurately, and avoids excessive false positives.
A tool that produces fewer but more reliable findings may be more valuable than one generating numerous low-quality comments.
Step 6: Test suggested fixes
Review whether proposed corrections actually resolve the identified problem.
Run tests and inspect whether fixes introduce unintended behavior.
This is especially important for security-sensitive code, where a plausible correction may create a new vulnerability.
Step 7: Calculate realistic costs
Estimate costs using actual developer counts, PR volumes, review frequency, and expected usage.
Include operational expenses and developer time spent evaluating findings.
Step 8: Assess enterprise controls
Verify support for administrative management, authentication, auditability, repository permissions, and policy enforcement.
Organizations with multiple engineering teams may also need centralized visibility into tool usage.
Step 9: Conduct a controlled pilot
Run shortlisted tools against the same evaluation dataset.
A pilot should be long enough to include ordinary feature changes, complex refactors, and security-sensitive modifications.
Step 10: Establish adoption criteria
Before rollout, define what would constitute success.
Possible criteria include improved detection of meaningful defects, acceptable review latency, reduced reviewer effort, and no unacceptable privacy or governance gaps.
A tool should be adopted because it meets these requirements, not because it performs well in a vendor demonstration.
Best AI code review tools by use case
Different development environments require different combinations of tools.
| Use case | Tools to evaluate | Selection rationale |
|---|---|---|
| Individual developer | GitHub Copilot, Cursor, Claude Code | Integrated coding assistance and review support |
| Small development team | CodeRabbit, GitHub Copilot code review, Qodo | Automated feedback within established PR workflows |
| GitHub-centric organization | GitHub Copilot code review, CodeRabbit | Native workflow integration and dedicated review options |
| Large interconnected codebase | Greptile, Qodo | Repository-context and cross-file analysis |
| Security-sensitive development | Semgrep, Snyk, SonarQube plus AI reviewer | Layered vulnerability and code-quality controls |
| Regulated enterprise | Tabnine, self-managed PR-Agent, approved security tools | Deployment control and governance considerations |
| Open-source project | PR-Agent, CodeRabbit, GitHub-native tools | Configurable automation and accessible review workflows |
| Team using coding agents extensively | Claude Code or Codex plus independent reviewer and CI checks | Separate code generation from verification |
These combinations are starting points for evaluation, not universal recommendations.
Recommended AI development stacks by organization type
A useful AI development stack should distribute responsibilities across generation, verification, security, and approval.
Individual developer
An individual developer may use a coding assistant such as GitHub Copilot or Cursor, local tests, and a lightweight AI review workflow.
The primary objective is to improve coding efficiency without introducing excessive complexity or subscription costs.
The developer remains responsible for understanding generated code and verifying its behavior.
Small software team
A small team may combine an IDE assistant, a dedicated PR reviewer, automated tests, and a static-analysis tool.
This arrangement can provide early feedback before changes reach senior reviewers.
The team should establish clear expectations for handling AI comments and ensure that automated review does not become an unnecessary approval bottleneck.
Large enterprise engineering team
A larger organization may need centralized tool administration, repository-level access policies, standardized review rules, security scanning, and audit records.
An enterprise stack might combine an approved coding assistant, repository-aware reviewer, SAST platform, dependency scanning, CI/CD quality gates, and mandatory code-owner approvals.
The objective is consistency across teams while preserving flexibility for different technology stacks.
Regulated or security-sensitive organization
A regulated enterprise should prioritize deployment architecture, data handling, access control, and evidence of review.
Private or self-managed tools may be appropriate when supported by the organization’s security requirements.
For critical code, AI-generated suggestions should be treated as untrusted changes until independently validated.
Teams adopting autonomous coding agents
Agent-heavy development requires additional controls because agents can perform actions rather than merely recommend code.
Such teams should separate the permissions used for code generation from those used for independent review and production deployment.
They should also maintain execution logs, sandbox agent activity, restrict credentials, and enforce human approval for consequential changes.
AI-assisted code generation and review: An enterprise workflow
A reliable development process should connect AI-assisted generation with multiple independent verification mechanisms.
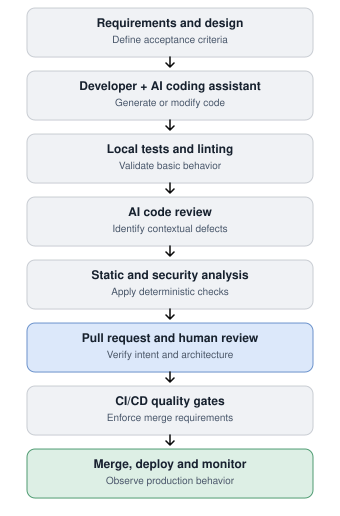
Reference workflow: AI-assisted software developmentConceptual workflow. Organizations can run some checks in parallel or repeat them after code changes.
Requirements and design
The workflow begins with clear requirements, acceptance criteria, and architectural constraints.
AI coding tools cannot reliably implement requirements that have not been adequately defined.
AI-assisted implementation
Developers may use coding assistants or agents to generate implementation code, tests, and documentation.
The output should be treated as a proposed change rather than an approved implementation.
Local validation
Developers should run relevant tests, formatting tools, and linters before submitting code.
This reduces the number of straightforward issues reaching automated and human reviewers.
AI-assisted review
An AI reviewer examines the proposed changes and identifies potential defects.
Its feedback should be evaluated based on correctness, severity, and relevance.
Static and security analysis
Deterministic analysis provides additional checks for known code-quality and security patterns.
These controls are particularly important when generated code introduces dependencies, external inputs, or sensitive operations.
Human review
Human reviewers evaluate whether the implementation meets requirements and aligns with system architecture.
They also assess tradeoffs that automated systems may not understand.
CI/CD enforcement
Automated quality gates ensure that required tests, scans, and approvals are completed before merging.
Deployment and monitoring
Review does not end when code is merged.
Production monitoring, incident analysis, and defect tracking provide feedback that can improve future coding and review practices.
How to evaluate AI code review tools: A practical methodology
Vendor demonstrations often use examples that highlight a product’s strengths. A more reliable evaluation uses controlled, representative code changes.
The objective is to measure whether the tool detects defects that matter in the organization’s development environment.
Build a representative evaluation dataset
Select a collection of pull requests from actual or realistically simulated development scenarios.
Include ordinary feature changes, bug fixes, refactors, security-sensitive modifications, and cross-file dependency changes.
Where possible, introduce known defects into a controlled test repository.
The evaluation should also contain correct code so that false-positive behavior can be measured.
Establish ground truth
A group of experienced developers or subject-matter experts should independently identify the known defects and their severity.
This provides a reference against which tool findings can be assessed.
Without ground truth, it is difficult to distinguish accurate detection from plausible but incorrect commentary.
Run each tool under comparable conditions
Use the same repository, pull requests, and available context.
Document configuration differences, model choices, and review settings.
Some products may require different integration methods, but the evaluation should minimize unnecessary variation.
Measure meaningful outcomes
| Metric | What it measures | Why it matters |
|---|---|---|
| Defect recall | Share of known defects detected | Indicates missed-defect risk |
| Finding precision | Share of reported findings that are valid | Indicates review noise |
| Severity accuracy | Whether findings are prioritized correctly | Helps teams focus on important issues |
| Cross-file detection | Ability to identify dependency-related defects | Tests repository understanding |
| Fix correctness | Whether suggested fixes resolve issues safely | Measures remediation usefulness |
| Review latency | Time required to produce feedback | Affects developer workflow |
| Developer triage effort | Time spent verifying comments | Reveals hidden productivity costs |
| Escaped defects | Problems reaching later stages | Indicates practical quality outcomes |
| Operating cost | Total cost of review activity | Supports purchasing decisions |
Calculate precision and recall
Two useful measures are:
\[ \text{Precision}=\frac{TP}{TP+FP} \]
\[ \text{Recall}=\frac{TP}{TP+FN} \]
Where:
- TP represents correctly identified defects.
- FP represents reported defects that are not real.
- FN represents known defects the tool failed to identify.
A reviewer with high recall but low precision may identify many genuine issues while overwhelming developers with incorrect comments.
A reviewer with high precision but low recall may provide trustworthy feedback while missing important defects.
The appropriate balance depends on the organization’s risk tolerance and review workflow.
Use a weighted evaluation scorecard
An organization can assign weights according to its requirements.
For example:
| Evaluation dimension | Illustrative weight |
|---|---|
| Defect detection and correctness | 25% |
| False-positive control | 15% |
| Repository context | 15% |
| Security and privacy | 15% |
| Workflow integration | 10% |
| Governance and administration | 10% |
| Cost and operational efficiency | 10% |
| Total | 100% |
These weights are illustrative, not an industry benchmark. A security-sensitive enterprise may assign substantially greater weight to privacy, access control, and vulnerability detection.
The resulting scores should support a documented decision rather than create an artificial impression of scientific precision.
Measuring the impact of AI code review
After adoption, engineering teams should determine whether AI review improves software quality and development efficiency.
The number of comments generated is not a sufficient success metric.
A useful measurement framework separates outcomes from process efficiency.
Quality outcomes
Track escaped defects, severity-weighted defects, security findings, and problems detected after deployment.
These indicators help determine whether review quality is improving.
However, changes in defect counts may reflect differences in release volume, application complexity, or reporting practices.
Review efficiency
Measure time from PR creation to first useful feedback, human review effort, time to merge, and time spent investigating incorrect findings.
A reduction in initial feedback time is useful only if it does not increase rework or escaped defects.
Developer experience
Collect structured feedback from developers about review usefulness, noise, clarity, and trust.
A tool that consistently produces irrelevant comments may be disabled or ignored even if it occasionally detects valuable defects.
Security and governance
Track compliance with review policies, security-gate outcomes, exceptions, and unauthorized tool usage.
These measures are particularly important for enterprises where source-code access and development processes are subject to formal controls.
Cost effectiveness
Evaluate licensing and operational costs against verified improvements in quality and workflow efficiency.
Avoid attributing every improvement to AI review without considering other changes in staffing, testing, architecture, or release processes.
When should organizations not rely on AI code review alone?
AI code review can improve coverage and provide useful feedback, but some software changes require stronger independent validation.
Security-critical code
Authentication, authorization, cryptographic implementations, and security-sensitive infrastructure require specialized review.
AI systems may overlook vulnerabilities that depend on threat models, deployment configurations, or adversarial behavior.
Financial and regulatory logic
Payment calculations, financial reporting, eligibility decisions, and regulatory workflows may involve requirements not represented in the source code.
A reviewer cannot reliably validate compliance with rules it has not been given.
Safety-critical systems
Software controlling physical systems or safety-related processes may require formal verification, specialized testing, and documented assurance procedures.
Generative AI feedback cannot replace those obligations.
Major architectural changes
Large migrations and architectural refactors can affect service boundaries, data consistency, latency, and operational reliability.
These consequences often require system-level understanding beyond the information available in a pull request.
Legacy systems with undocumented dependencies
Older applications may contain behavior that is intentional but poorly documented.
An AI reviewer may recommend changes that appear cleaner while breaking important compatibility assumptions.
Ambiguous requirements
If the intended behavior is unclear, an AI reviewer may validate code against an incorrect assumption.
Requirements clarification must precede meaningful correctness assessment.
In these situations, AI review should serve as supplementary evidence rather than the final authority.
Common mistakes when adopting AI coding and review tools
Several adoption mistakes can undermine the expected benefits.
Treating AI review as a replacement for human review. Automated systems can identify useful issues, but they do not assume responsibility for architectural decisions, business requirements, or production risk.
Allowing overly permissive agent access. Coding agents should not receive unrestricted repository or production permissions merely for convenience.
Measuring success through comment volume. A large number of findings can indicate poor precision rather than strong detection.
Ignoring licensing and intellectual-property considerations. Organizations should establish policies for generated code, dependencies, and external processing of proprietary source.
Using one tool for every development requirement. Coding assistance, security analysis, PR review, and quality enforcement are related but distinct activities.
Failing to reassess tools. AI development products change quickly. Integrations, models, pricing, and governance capabilities should be reviewed periodically.
What comes next for AI-assisted code review?
Several developments are worth monitoring as AI-assisted software engineering becomes more integrated into development workflows.
Greater emphasis on repository context
Review systems are increasingly being evaluated on whether they can reason about dependencies beyond the immediate diff.
The challenge is not simply retrieving more code, but identifying the context necessary to understand the consequences of a change.
Closer integration between coding agents and reviewers
Coding agents can generate and modify code, while review systems can provide feedback that leads to further changes.
This creates opportunities for iterative development workflows.
However, organizations should avoid assuming that a system can independently verify its own work without meaningful risk.
More configurable review policies
Teams may increasingly expect review tools to apply repository-specific instructions, severity thresholds, and organizational conventions.
The practical value will depend on how consistently those controls operate and whether they can be audited.
Stronger governance expectations
As AI tools gain access to repositories, terminals, and deployment environments, organizations will need clearer controls over identity, permissions, execution, and accountability.
The direction of development is toward more integrated assistance, but integration should not come at the expense of independent verification.
Conclusion
AI code generation and code review address complementary challenges in software engineering. Coding assistants and agents can accelerate implementation, while AI reviewers can help identify defects, explain potential risks, and provide earlier feedback within development workflows.
However, the value of AI code review should not be measured by how many comments a tool generates or how quickly it completes a pull-request analysis. The more meaningful questions are whether it identifies consequential defects, understands relevant repository context, produces reliable suggestions, and reduces review effort without introducing additional risk.
For individual developers and smaller teams, integration simplicity, affordability, and actionable feedback may be the most important selection criteria. Larger organizations must also consider source-code confidentiality, repository permissions, auditability, deployment architecture, and consistency across engineering teams.
Dedicated reviewers such as CodeRabbit, Greptile, Qodo, and Cursor Bugbot offer different approaches to automated review. GitHub Copilot provides an integrated option for GitHub-based development, while SonarQube, Semgrep, and Snyk address complementary code-quality and security requirements. Coding agents such as Claude Code and Codex extend the development workflow further by helping execute multi-step engineering tasks.
The most dependable approach is therefore not to select one AI tool and expect it to manage the entire software lifecycle. It is to build a layered process in which AI-assisted generation, contextual review, automated testing, deterministic security analysis, and human engineering judgment reinforce one another.
The objective is not merely to generate and review code faster. It is to deliver software that meets requirements, remains maintainable, and satisfies the organization’s quality, security, and governance standards.
Frequently asked questions
What is the best AI code review tool in 2026?
There is no universal best tool. CodeRabbit, Greptile, Qodo, GitHub Copilot code review, and Cursor Bugbot are relevant candidates for automated review. The appropriate choice depends on repository context, integration requirements, review quality, privacy, and cost.
Can AI review code automatically?
Yes. AI code review systems can analyze pull requests and produce comments, summaries, and suggested fixes. However, automated feedback should be verified, particularly for security-sensitive and business-critical code.
Can ChatGPT or Claude review code?
Yes. General-purpose AI assistants can analyze code supplied through prompts or connected development workflows. However, an interactive review is not automatically equivalent to a dedicated PR-review system with repository integration, review history, and administrative controls.
Is AI code review reliable?
AI review can identify meaningful defects, but reliability varies by tool, codebase, context, and defect type. False positives and missed defects remain possible. Organizations should evaluate tools against representative code changes containing known issues.
Can AI code review replace human reviewers?
AI can reduce some repetitive review effort, but it should not replace human accountability for requirements, architecture, security, and production risk. Human review is especially important for high-impact changes.
What is the difference between AI code review and static analysis?
AI code review commonly uses generative models to reason about code and explain potential issues. Static analysis uses program-analysis techniques and rules to detect supported patterns without executing the application. The two approaches complement each other.
Which AI code review tools work with GitHub?
GitHub Copilot code review, CodeRabbit, Greptile, Qodo, and several other review platforms offer GitHub-oriented workflows. Integration capabilities and enterprise-hosting support should be checked against current product documentation.
Are there free AI code review tools?
Yes. Open-source projects such as PR-Agent provide options for customized review automation. Some commercial vendors also offer limited free plans or trials. Users should examine usage restrictions and model-processing costs.
Can AI code review detect security vulnerabilities?
AI review may identify insecure patterns, but it should not be the only security control. Organizations should combine it with appropriate SAST, dependency scanning, secret detection, testing, and human security review.
Is it safe to connect AI code review tools to private repositories?
Safety depends on the vendor’s data-handling practices, access controls, deployment model, and the organization’s requirements. Before granting access, review permissions, retention policies, model providers, and contractual protections.
What is the difference between an AI coding assistant and an AI code reviewer?
An AI coding assistant primarily helps developers create or modify code. An AI code reviewer primarily evaluates existing or proposed changes. Some products provide both capabilities, but generation and verification remain distinct functions.